Why NIR needs chemometrics: PCA, PLS and PCR explained
Short answer: NIR chemometrics is the maths that turns a raw spectrum into a number. A spectrum holds hundreds of correlated absorbance values built from overlapping C-H, O-H and N-H overtone and combination bands, so no single wavelength can be read as a protein or moisture value. Principal component analysis (PCA) compresses and explores that data, partial least squares (PLS) regression links it to reference values, principal component regression (PCR) does the same in two separate steps, and preprocessing strips out the physical variation before any model is fitted.
Without chemometrics, a modern spectrometer is just a very expensive light sensor. That is not a knock on the hardware; it is the nature of the measurement. The chemistry is all there in the spectrum, mixed together, and the job of the model is to pull out the one piece you asked for.
I have seen a receiving lab load a factory calibration, watch numbers that looked reasonable, and assume the work was finished, only to find moisture drifting across a season. The instrument was fine. The chemistry, and the model behind the number, had not caught up with the samples arriving at the door. The sections below walk through the techniques that make the number possible, in the order a beginner meets them: why the spectrum is unreadable, what PCA shows you first, how PLS and PCR build the calibration, which preprocessing to apply, and how validation tells you the model still works.
Why does NIR need chemometrics at all?
Because the instrument alone is not the answer. A raw NIR spectrum holds hundreds of correlated absorbance values, and almost every organic bond in the sample writes into the same regions: overlapping overtone and combination bands from C-H, O-H and N-H vibrations pile on top of one another, and physical effects such as particle size, baseline shift and temperature mask the chemistry further. You cannot read a protein or moisture number off that trace; no single wavelength belongs to one compound.
Chemometrics is the layer that makes the number possible. It separates the overlapping signals, removes the unwanted variation that has nothing to do with chemistry, and builds a stable link between the spectrum and a reference value measured in the lab. The sections below walk through how that works, from the first look at the data with PCA to the regression that predicts a value and the validation that proves it holds.
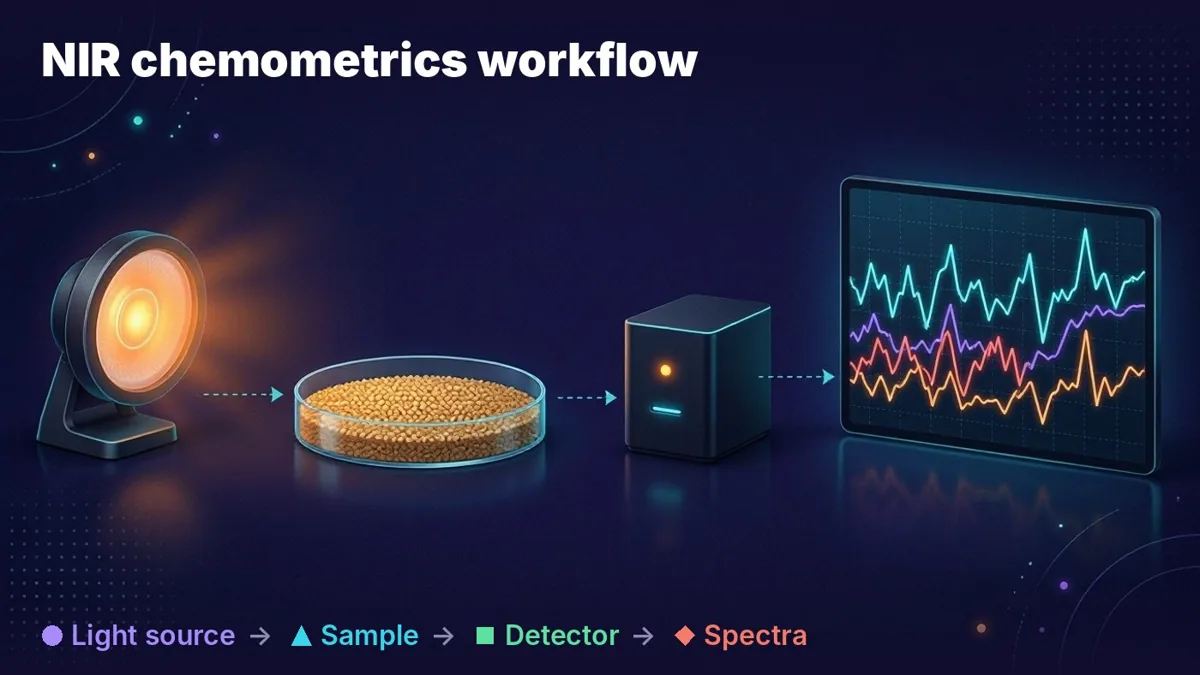
Why NIR needs chemometrics: PCA, PLS and PCR explained
Short answer: NIR chemometrics is the maths that turns a raw spectrum into a number. A spectrum holds hundreds of correlated absorbance values built from overlapping C-H, O-H and N-H overtone and combination bands, plus physical effects such as particle size and baseline shift, so no single wavelength can be read as a protein or moisture value. Principal component analysis (PCA) compresses and explores that data, partial least squares (PLS) regression links it to reference values, principal component regression (PCR) does the same in two separate steps, and preprocessing strips out the physical variation before any model is fitted.
Why can't you read a protein or moisture value straight from a spectrum?
Because the value is buried under two kinds of clutter at once. The first is chemistry: the C-H, O-H and N-H overtone and combination bands of almost every organic compound in the sample fall across the same NIR range and pile on top of each other, so hundreds of correlated absorbance values each carry a mixture rather than one substance (Beć 2021). The second is physics: a baseline shift, a finer or coarser grind, or a few degrees of sample temperature change the absorbance without changing the protein.
The interactive below makes the point directly. Widen the simulated bands, or add more of them, and the individual features merge into one smooth envelope. Nothing has left the spectrum; the chemistry is still in there, but no eye and no single wavelength can separate it. A model is what resolves the pattern.
A temperature shift is not a small effect on a mixed signal. When the model was not built to cope with it, a modest change in sample temperature is enough to move a moisture prediction by a fraction of a percent, which is the same order as the difference you are trying to measure. The instrument has not failed. The signal is mixed, and mixing is the normal condition of an NIR spectrum.
Overlap, not sensitivity, is the limit. A spectrum is a sum of many contributions. Chemometrics is how that sum is taken apart.
What does PCA do before any model is built?
Before I fit anything, I want to see the shape of the data. Principal component analysis (PCA) is unsupervised: it never looks at the reference values, so it cannot be biased toward the answer I hope to get. It compresses the many correlated absorbance values at each wavelength into a few principal components — the handful of directions that describe how these samples actually differ.
Two things come out of that first look. The score plot shows how samples sit relative to each other, so a different crop year, origin or supplier often separates into its own cluster before any chemistry is involved. And a sample far from the rest of the cloud is an outlier: a mislabelled jar, a contaminated batch, a bad scan. Catching that here is far cheaper than discovering it after the model has learned it.
How does PLS turn spectra into a calibration?
Partial least squares (PLS) is the workhorse of quantitative NIR. Unlike PCA, it is supervised: it uses the reference values from wet chemistry while it builds its components, called latent variables, so each one is chosen to predict the property you care about rather than just to describe the spectrum. That is how PLS turns spectra into a calibration — it compresses the collinearity of NIR data into a handful of latent variables that link spectrum to reference value, which is why it is the usual first choice for protein, moisture and fat calibrations (Cui & Fearn 2017; Fearn 2011).
More factors is not better. A PLS model stops improving once it starts memorising noise: the calibration error keeps shrinking while the cross-validated error climbs. Pick the factor count at the valley, not the end of the curve.
How is PCR different from PLS?
PCR and PLS both finish with a regression on a few components, but they choose those components differently. PCR runs PCA first, on the spectra alone, with no reference values involved. It keeps the directions that explain the most spectral variation, then regresses the property on those components. PLS builds each component while looking at the reference values, so it keeps the directions that predict protein or moisture, not merely the ones that vary most.
That difference usually shows up as model size. Every PCR component is chosen blind to the property, so the first few often describe variation that has nothing to do with the analyte, and more components are needed to reach a given error. PLS concentrates the predictive information early, so it typically needs fewer components for the same result. Yaroshchyk et al. (2012) make the same comparison when contrasting PCR and PLS on spectral data.
PCR still earns a place as a comparison. If a PLS model underperforms, a PCR model on the same preprocessed data gives a reference point: when PCR needs many more components to approach the same error, the property is carried by spectral structure that PCA alone does not rank highly, and the gap tells you where to look next.
Same regression, different components. PCR asks which directions vary most; PLS asks which directions predict the property. For NIR calibration, that second question is usually the one worth answering first.
Which preprocessing should you apply before the model?
Preprocessing is a modelling decision, not a rescue step. SNV, MSC, derivatives and mean centering each target a different physical effect: scatter from particle size, a broad baseline offset, overlapping bands, or a constant level the model does not need. The choice decides how well a calibration survives a new grinder, a second instrument or a new season. The table compares what each method corrects and when I reach for it.
| Method | What it corrects | When it is used |
|---|---|---|
| Standard normal variate (SNV) | scatter from particle size and fill, sample by sample | ground grain and feed where grind varies between samples or sites |
| Multiplicative scatter correction (MSC) | baseline offset and scaling differences against a reference spectrum | scatter dominates; needs a clean reference and is sensitive to outliers |
| Derivatives (1st, 2nd) | broad baseline shifts; sharpens overlapping bands | bands overlap and baselines drift, common in grain and feed |
| Mean centering | a constant offset carrying no predictive information | before regression, in almost every PLS workflow |
A strong fit on the calibration set can hide a preprocessing mismatch. A model built without scatter correction can look good on one grinder and fail on a coarser grind at another site. Pick preprocessing for the variation you expect to meet, then prove it on samples the model has not seen.
ILLUSTRATIVE A made-up feed lab to show the reasoning: a protein calibration built without SNV on finely ground samples reads well until a second site grinds coarser and predictions scatter. Adding SNV and rebuilding brings the error back down without new reference samples. Scatter correction targeted the physical variation; it did not touch the chemistry.
How do you know the model works, and when does it stop working?
A calibration is only as good as the evidence that it predicts samples it has never seen. That evidence is itself chemometric output: RMSECV, RMSEP, R squared and RPD, read together rather than one at a time. RMSECV is the cross-validated error inside the calibration set; RMSEP is the error on independent samples the model was not tuned on. The gap between the two is the honest test, because a model that has memorised its calibration set shows a small RMSECV and a much larger RMSEP (Zhao et al. 2016).
Even a validated model has a boundary. Score each new sample against the calibration space, and samples that fall outside it show that the population has drifted; that is the point to add referenced samples and rebuild, not to keep trusting the number.
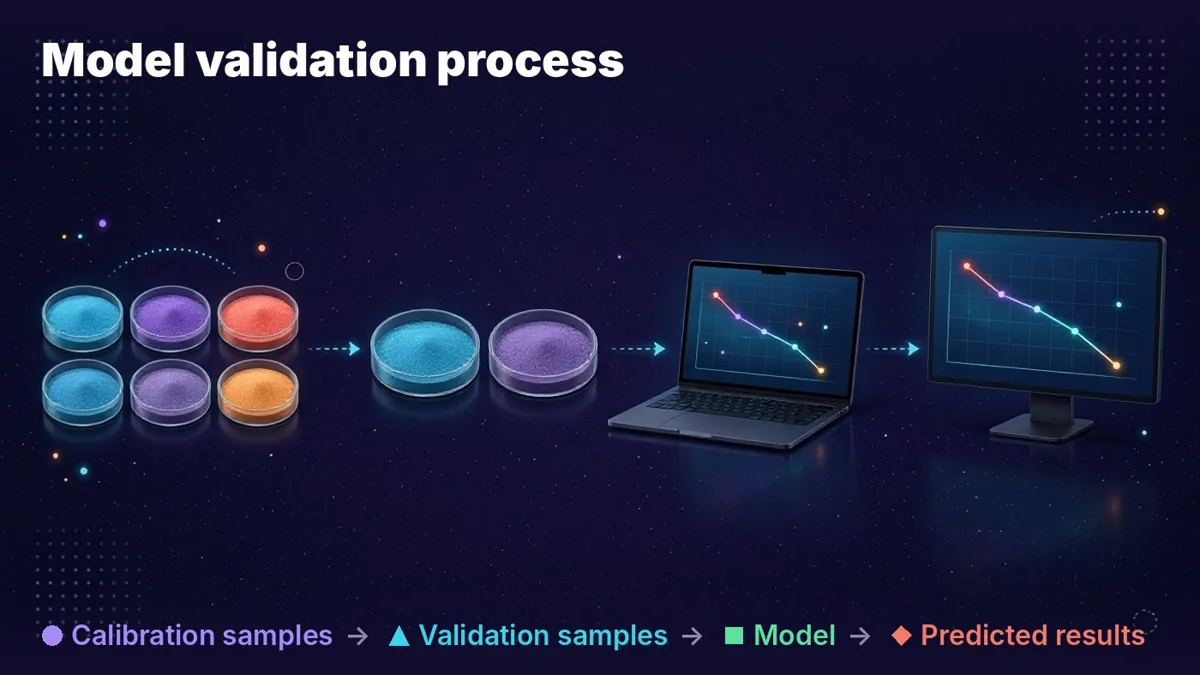
A strong R squared can hide a large validation gap. An R squared of 0.98 on the calibration set means little if RMSEP on independent samples is several times the RMSECV. Judge the model on samples it has not seen, not on how well it fits the ones it has. ILLUSTRATIVE
Worked example: a protein model that holds across a season
ILLUSTRATIVE A made-up feed mill, used only to show the reasoning; not a customer case.
A mill builds a protein calibration on finished-feed samples with wet-chemistry references. PCA on the calibration set, run before any regression, shows one tight cloud with two points sitting far outside it; both turn out to be a mislabelled batch, and they are set aside before the model is fitted. PLS is then built, and the cross-validated error falls steeply for the first five factors and flattens after that, so five is the number kept: each extra factor lowers the training error while the validation error stops improving — the classic sign of fitting noise.
Six months later the grinder is replaced and routine samples start reading high. The spectra show a slope in the baseline rather than a wavelength shift, so SNV is added ahead of the model and the calibration is refitted on the same samples. Validation on samples the model has never seen brings the error back to where it started, and the mill keeps a standing check of a few referenced samples each week.
Quick check
Step 6 of 6: Why NIR needs chemometrics
- 1How NIR light worksLight, bonds and why NIR needs little prep.Read part 1 →
- 2What it measures, where it failsReliable analytes, limits and sample presentation.Read part 2 →
- 3Inside the instrumentLight source, sample interface, detector.Read part 3 →
- 4Molecular vibrationsOvertones and combination bands in depth.Read part 4 →
- 5Beer-Lambert and its limitsWhy absorbance is not simply proportional in NIR.Read part 5 →
- 6Why NIR needs chemometricsYou are here.Current
Frequently asked questions
What is chemometrics in NIR spectroscopy?
Chemometrics is the set of mathematical and statistical methods that turn a raw NIR spectrum into a chemical value. It covers preprocessing, exploratory methods such as PCA, and regression methods such as PLS and PCR, plus the validation statistics that show whether the result can be trusted.
Why do NIR spectra need chemometrics at all?
NIR spectra contain overlapping C-H, O-H and N-H overtone and combination bands, so almost every organic compound contributes to every region. On top of that, particle size, baseline shifts and temperature change the spectrum in ways unrelated to chemistry. Neither problem can be solved by reading a single wavelength.
What is the difference between PLS and PCR?
Both reduce the spectrum to a few components before regressing. PCR runs PCA first, ignoring the reference values, then regresses on those components. PLS builds components that are chosen to predict the reference value, which is why it is the usual choice for NIR calibration.
Is PCA supervised or unsupervised?
PCA is unsupervised: it needs no reference values. It finds the directions of greatest variation in the spectra, which makes it useful for spotting groupings and outliers before any regression is attempted.
What does preprocessing do in an NIR calibration?
Preprocessing removes variation that is physical rather than chemical, such as scatter from particle size or a shifting baseline. Standard normal variate, multiplicative scatter correction, derivatives and mean centering are the common choices, and the choice affects how well a model survives a new grinder, instrument or season.
Which chemometric method is best for NIR?
There is no single best method. PLS is the most widely used for quantitative calibration because it handles the collinearity of NIR data well. PCA is the usual first look at a dataset, PCR is a useful comparison, and classification or nonlinear methods are chosen when the task calls for them.
Next questions people ask
Learn the maths that makes NIR work
The course covers preprocessing, PCA, PLS, PCR and validation in 32 short lessons for food, grain, feed and dairy labs. One payment, lifetime access.
Sources
- Dhanoa, M.S. et al., "The Link between Multiplicative Scatter Correction (MSC) and Standard Normal Variate (SNV) Transformations of NIR Spectra", Journal of Near Infrared Spectroscopy 1994. doi:10.1255/jnirs.30
- Cui, Chenhao et al., "Comparison of partial least squares regression, least squares support vector machines, and Gaussian process regression for a near infrared calibration", Journal of Near Infrared Spectroscopy 2017. doi:10.1177/0967033516678515
- Fearn, Tom, "Partial Least Squares Regression versus Multiple Linear Regression", NIR news 2011. doi:10.1255/nirn.1252
- Beć, Krzysztof B, "A Simple guide to complex world of overtone and combination bands: Theoretical simulation and interpretation of NIR spectra – summary of the workshop at NIR-2021 Beijing Conference", NIR news 2021. doi:10.1177/09603360211060966
- Zhao, Na et al., "MDL and RMSEP assessment of spectral pretreatments by adding different noises in calibration/validation datasets", Spectrochimica Acta Part A: Molecular and Biomolecular Spectroscopy 2016. doi:10.1016/j.saa.2016.03.017